Reinventing Organizations Redux

This one is a bit out there, if only to connect some dots and shake loose new insights. Let’s get that distant look in our eyes and contemplate a possibility that may or may not transpire. Let’s all suppose that the upcoming AI winter is mild, and we settle into the next local maxima of technological progress, surrounded by helpful semi-autonomous agents, powered by large language models. What might that look like?
A teal butterfly sitting on white keyboard, a tribute to Laloux's book cover

I am pretty sure I got the firmness of the performance asymptote wrong last May. The superlinear relationship between quality and cost is here to stay, and will shape a step-ladder-like differentiation of models based on their size. There will be larger models that produce high-quality results for a wide diversity of tasks  – and are also expensive to run. There will be smaller models that are much, much cheaper, but also can only excel at a narrow task. We are likely to see attempts to establish a common scale for model complexity, rather than one model to rule them all.

Given that, we are likely to see more emphasis on the scaffolding that connects the models of varying sizes in addition to the models themselves. For instance, many startups and larger companies are already experimenting with the “inverted matryoshka” scaffolding, where a set of models is arranged so that the smaller, cheaper models are used more frequently for the simpler tasks and the largest models are only progressively reached for more complex (and hopefully, more rare) tasks.

Sure, there will be projects that try to hide that scaffolding under a “universal model”, which upon examination, will reveal a trenchcoat filled with the assortment of models, pretending to be one. 

However, driven by the desire for agency, most will choose to rely on their access to this scaffolding to get better results. The scaffolding will be the secret sauce of success. The way we arrange the models – and how we choose and train the models for particular tasks  – will continue to be the subject of intense experimentation and optimization, even when the pace of model innovation slows down.

This last sentence holds a startling realization. If we consider that each model is a “knowledge worker” of sorts, we can view the aforementioned scaffolding as an organization. If that’s the case, we can now imagine the process of creating and managing a collection of models as organization development. Except in this organization, the majority of workers are large language models.

Already, we see academic papers suggesting waterfall-like approaches to tasks, where multiple models (also known as agents) are lined in an assembly line of sorts, passing their output to the next one. I am also seeing experiments with parallel workstreams, converging together to be ranked. Each of the juncture points in these flows is a “virtual knowledge worker”. Perhaps not in the way Frederic Laloux intended, we are reinventing organizations.

It is quite possible (likely?) that organizations we will work in will include both human and non-human workers in them. These organizations will face the same challenges that any organization will face, and likely more new challenges that we haven’t even considered. There will be levels. Simple tasks performed by armies of lower-nomenclature model-powered workers (we’ll probably call them bots). More complex tasks performed by more expensive models. People will likely be supervising, directing, or tuning knowledge work. There might be an entirely new discipline of virtual organization development that emerges as a way of studying and finding more effective ways to conduct organizations that include model-based agents as part of their workforce.

This may not come to pass. However, what feels right in this picture is that humans will still be there. And because we are unpredictable, volatile humans, who come and go, who change our minds – there will always be a need to maintain a semblance of predictability around the business that owes the organization its existence. And because of that, the relatively more predictable and malleable workers might just serve as the organization development putty: keep adjusting the mixture of non-human workers in the organization to retain its strengths as people leave and join the organization – or change within it.

Perhaps in this future, we will ask not the question of whether or not AI will replace humans – but rather the question of how non-human knowledge workers can scaffold around us  in a way that complements our gifts and gives us space to develop and grow.

The Breadboard developer cycle

Over the past couple of months, we’ve been working on a bunch of new things in the Breadboard project, mostly situated around developer ergonomics. I’ve mentioned creating AI recipes a bunch in the past, and it might be a good time to talk about the mental model of how such recipes are actually created.

❤️‍🔥 Hot reload 

One of the Breadboard project design choices we’re leaning into is the “hot reload” pattern. “Hot reload” is fairly common in the modern developer UX, and we’d like to bring it into the realm of AI recipes. In this pattern, the developer sees not just the code they write, but also results of this code running, nearly instantaneously. This creates a lightning-fast iteration cycle, enabling the developer to quickly explore multiple choices and see which ones look/work better.

Most “hot reload” implementations call for two surfaces that are typically positioned side by side: one for writing the source code, and another for observing the results. In Breadboard today, the first one is typically an editor (I use VSCode) and the second one is our nascent Breadboard debugger.

As the name “hot reload” signifies, when I save the source code file in my editor, the debugger automatically reloads to reflect the recent changes.

The typical workflow I’ve settled into with Breadboard is that I start writing the board and get it to some point where it has enough to do at least something, I save the file and play with the board in the debugger. Playing with it both informs me whether I am on the right path and gives me ideas on what to do next.

I then act on this feedback, either fixing a problem that I am seeing, or progressing forth with one of the ideas that emerged through playing.

For my long-time readers: yes, we’ve baked the OODA loop right into Breadboard.

Overall, it’s a pretty fun experience. I get to see the board rising out of code by iteratively playing with it.

🪲 Debugger

To enable this fun, Paul Lewis has been doing the magician’s work bringing up the debugger. It’s very much a work in progress, though even what’s there now is already useful for board-making.

The main purpose of the debugger is to provide both the visualization of the AI recipe that is being developed and the process of it running. As I put it in chat, I love “seeing it run”: I get to see and understand what is happening during the run — as it happens! – and dig into every bit of detail.

There’s even a timeline that I can scrub through to better help me understand how events unfolded.

One thing that gives Breadboard its powers is that it’s built around a very flexible composition system. This means that my recipes may reach for other recipes during the run – sometimes a whole bunch of them. Reasoning about that can be rather challenging without help. As we all know, indirection is amazing until we have to spelunk the dependency chains.

To help alleviate this pain, the Breadboard debugger treats recipe invocations as the front-and-center concept in the UI. The timeline presents them as layers, similar to the layers in photo/video/sound editing tools. I can walk up and down the nested recipes or fold them away to reduce cognitive load.

There’s so much more work that we will be doing here in the coming weeks and my current description of the Breadboard debugger is likely to become obsolete very quickly. However, one thing will remain the same: the iteration speed is so fast that working with Breadboard is joyful.

🧸 Exploration through play

This leads me to the key point of what we’re trying to accomplish with the development cycle in Breadboard: exploring is fun and enjoyable when the iterations are fast and easily reversible.

This is something that is near and dear to my heart. 

When the stakes in exploration are high, we tend to adopt a defensive approach to exploring: we prepare, we train, and brace ourselves when it is the time to venture out into the wilderness. Every such exploration is a risky bet that must be carefully weighted, and uncertainty reduced as much as possible.

When the stakes of exploration are low, we have a much more playful attitude. We poke and prod, we try this and that, we goof around. We end up going down the paths that we would have never imagined. We end up discovering things that couldn’t have been found by an anxious explorer.

It is the second kind of exploration that I would love to unlock with Breadboard. Even when learning Breadboard itself, I want our users to have the “just try it” attitude: maybe we don’t know how this or that node or kit works. Maybe we don’t have an answer to what parameters a recipe accepts. So we just try it and see what happens – and get reasonable answers and insights with each try.

If you’re excited about the ideas I wrote about here, please come join us. We’re looking for enthusiastic dance partners who dream of making the exploration of AI frontiers more accessible and enjoyable.

Declarative vs. imperative

I recently had a really fun conversation with a colleague about “declarative vs. imperative” programming paradigms, and here’s a somewhat rambling riff that I captured here as a result.

When we make a distinction between “declarative” and “imperative” programming, we usually want to emphasize a certain kind of separation between the “what” and the “how”. The “what” is typically the intention of the developer, and the “how” is the various means of accomplishing the “what”.

For me, this realization came a while back, from a chat with Sebastian Markbåge in the early days of React, where he stated that React is declarative. I was completely disoriented, since to me, it was HTML and CSS that were declarative, and React was firmly in the imperative land.

It took a bit of flustering and a lot of Sebastian’s patience for me to grok that these terms aren’t not fixed. Rather, they are a matter of perspective. What might seem like “you’re in control of all the details” imperative from one vantage point will look completely declarative from another.

📏 The line between the “what” and the “how” 

Instead of trying to puzzle out whether a given programming language, framework, or paradigm is declarative or imperative, it might be more helpful to identify the line that separates the “what” and the “how”.

For instance, in CSS, the “what” is the presentation of an HTML document (technically a DOM tree), and the “how” is the method by which this presentation is applied. In CSS, we declare what styling attributes we would like each document element to look like, and leave the job of applying these styles to the document in the capable hands of CSS.

Similarly, in React, we declare the structure of our components and their relationship to the state, while leaving the actual rendering of the application up to the framework.

Every abstraction layer brings some “declarativeness” with it, shifting the burden of having to think about some the implementation details from the shoulders of the developer into the layer.

If we look carefully, we should be able to see the line drawn between the “how” and the “what” in every abstraction layer.

In drawing this line, the creators of an abstraction layer – whether they are intentional about it or not – make a value judgment. They decide what is important and must remain in developer’s control, and what is not as important and could be abstracted away. I called this value judgment “an opinion” earlier in my writings.

One way to view such a value judgment is as a bet: it is difficult to know ahead of time whether or not the new abstraction layer will find success among developers. The degree of opinion underlines the risk that the bet entails. More opinionated abstraction layers make riskier bets than less opinionated ones.

If we measure reward in adoption and long-term usage, then the higher risk bets also promise higher reward: the degree of difference in opinion can serve as a strong differentiator and could prove vital to the popularity of the layer. In other words, if our layer isn’t that different from the layer below, then its perceived value isn’t that great to a developer.

Therein lies the ancient dynamic that underlies bets (or any value judgments, for that matter): when designing layers of abstraction, we are called to find that balance of being different enough, yet not too different from the layer below.

🪢 The rickety bridge of uncertainty

While looking for that balance, one of the most significant and crucial exercises that any framework, language, or programming paradigm will undertake is the one of value-trading with their potential developers.

This exercise can be described by one question: What is it that a developer needs to give up in order to unlock the full value of our framework?

Very commonly, it’s the degree of control. We ask our potential developers to relinquish access to some lower-layer capabilities, or perhaps some means to influence control flow.

Sometimes (and usually alongside with lesser control), it’s the initial investment of learning time to fully understand and gain full dexterity of wielding the layer’s opinion.

Whatever the case, there is typically a rickety bridge of uncertainty between the developer first hearing of our framework and their full-hearted adoption.

I once had the opportunity to explain CSS to an engineer who spent most of their career drawing pixels in C++, and they were mesmerized by the amount of machinery that styling the Web entails. If all you want to draw is a green box in the middle of the screen, CSS is a massively over-engineered beast. It is a long walk across unevenly placed planks to the point where the full value of this machinery even starts to make sense, value-wise. Even then, we’re constantly doubting ourselves: is this the right opinion? Could there be better ways to capture the same value?

This bridge of uncertainty is something that every opinionated layer has to cross. Once the network effects take root, the severity of the challenge diminishes significantly. We are socialized species, and the more people adopt the opinion that the abstraction layer espouses, the more normal it becomes – perhaps even becoming the default, for better or worse.

🧰 Bridging techniques

If we are to build abstraction layers, we are better off learning various ways to make the bridge more robust and short.

One technique that my colleague Paul Lewis shared with me is the classic “a-ha moment”: structure our introductions and materials in such a way that the potential value is clearly visible as early as possible. Trading is easier when we know what we’re gaining.

This may look like a killer demo that shows something that nobody else can do (or do easily). It may look like a tutorial that begins with a final product that just begs to be hacked on and looks fun to play with. It could also be a set of samples that elegantly solve problems that developers have.

Another technique is something that Bernhard Seefeld is actively experimenting with: intentionally designing the layer in such a way that feels familiar at first glance, but allows cranking up to the next level – incrementally. You can see this work (in progress 🚧) in the new syntax for Breadboard: it looks just like a typical JS code at first, rapidly ramping up to graph serialization, composition, and all the goodies that Breadboard has to offer.

I am guessing that upon reading these examples, you immediately thought of a few others. Bridging techniques may vary and the technique playbook will keep growing, but one thing that unites them all is that they aim to help developers justify the trade of their usual conveniences for the brave new world of the layer’s opinion.

Designing new layers is an adventure with the indeterminate outcome. We might be right about our value judgments, or we might be wrong. It could be that no matter how much we believe in our rightness, nobody joins to share our opinion with us. No technique will guarantee the outcome we wish for. And that’s what makes API design and developer experience work in general so fun for me. 

Hourglass model and Breadboard

Architecturally, Breadboard aspires to have an hourglass shape to its stack. As Bernhard Seefeld points out, this architecture is fairly common in compilers, and other NLP tools, so we borrowed it for Breadboard as well.

In this brief essay, I will use the Breadboard project to expand a bit on the ins and outs of the hourglass-shaped architecture.

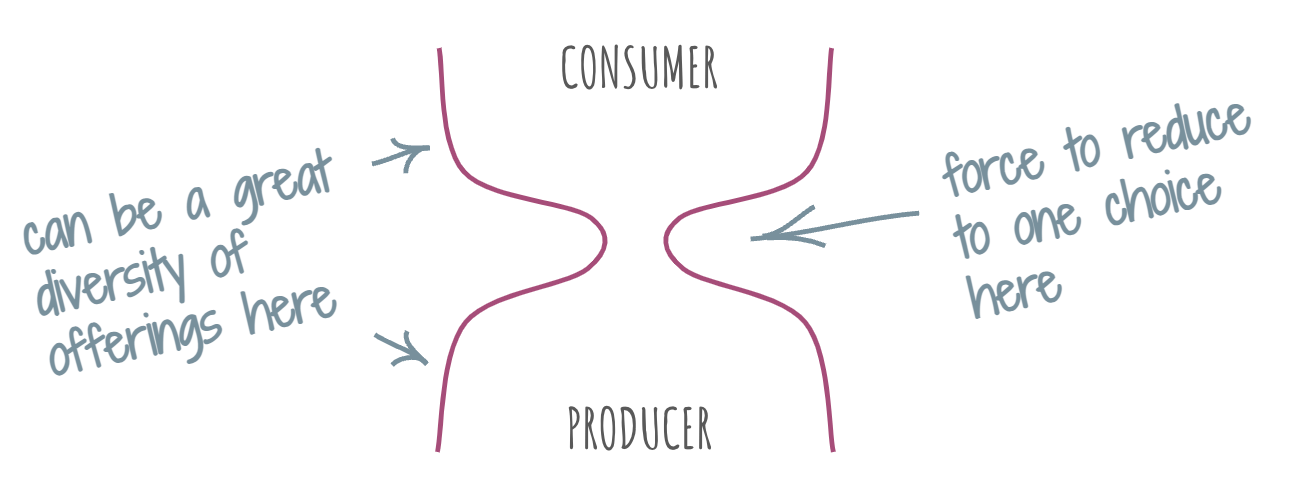
At the waist of the hourglass, there’s a  single entity, a common format or protocol. In Breadboard, it is a JSON-based format that we use to represent any AI recipe (I called them AI patterns earlier, but I like the word “recipe” better for its liveliness). When you look through the project, you’ll notice that all recipes are JSON files of the same format. 

The actual syntax of the JSON file may change, but the meaning it captures will stay the same. This is one of the key tenets of designing an hourglass stack: despite any changes around it, the semantics of the waist layer must stay relatively constant.

The top part of the hourglass is occupied by the recipe producers, or “frontends” in the compiler lingo. Because they all output to the same common format, there can be a great variety of these. For example, we currently have two different syntaxes for writing AI recipes in TypeScript and JavaScript. One can imagine a designer tool that allows creating AI recipes visually. 

Nothing stops someone from building a Python or Go or Kotlin or any other kind of frontend. As long as it generates the common format as its output, it’s part of the Breadboard hourglass stack.

The bottom part of the stack is where the recipe consumers live. The consumers, or “backends”, are typically runtimes: they take the recipe, expressed in the common format and run it. At this moment in Breadboard, there’s only a Javascript runtime that runs in both Node and Web environments. We hope that the number of runtimes expands. For instance, wouldn’t it be cool to load a Breadboard recipe within a colab? Or maybe run it in C++? Breadboard strives for all of these options to be feasible.

Runtimes aren’t the only kinds of backends. For instance, there may be an analysis backend, which studies the topography of the recipe and makes some judgments about its integrity or other kinds of properties. What sorts of inputs does this recipe take? What are its outputs? What are the runtime characteristics of this recipe?

Sometimes, it might be challenging to tell a backend apart from a frontend: an IDE may include both frontends (editor, compiler, etc.) and backends (runtime, debugger, etc.). However, it’s worth drawing this distinction at the system design stage.

The main benefit of an hourglass stack design is that it leaves a lot of room for experimentation and innovation at the edges of the stack, while providing enough gravitational pull to help the frontends and backends to stick together. Just like for any common language or protocol, the waist of the hourglass serves as a binding agreement between the otherwise diverse consumer and producer ideas. If this language or protocol is able to convey valuable information (which I believe we do with AI recipes in Breadboard), a network effect can emerge under the right conditions: each new producer or consumer creates combinatorial expansion of possibilities – and thus, opportunities for creating new value – within the stack.

It is far too early to tell whether we’ll be lucky enough to create these conditions for Breadboard, but I am certainly hopeful that the excitement around AI will serve as our tailwind.

The key risk for any hourglass stack is that it relies on interoperability: the idea that all consumers and producers interpret the common format in exactly the same way. Following the Hyrum’s Law, any ambiguity in the semantics of the format will eventually result in disagreements across the layers.

These disagreements are typically trailing indicators of the semantic ambiguities. By the time the bugs are identified and issues are filed, it is often too late to fix the underlying problems. Many languages committees spend eons fighting the early design mistakes of their predecessors.

As far as I know, the best way to mitigate this risk is two-fold. We must a) have enough experience in system design to notice and address semantic ambiguities early and b) have enough diversity of producers and consumers within the hourglass early in the game.

To be sure, a system design “spidey sense”, no matter how well-developed, and the ability to thoroughly exercise the stack early don’t offer 100% guarantees. Interoperability tends to be a long-term game. We can flatten the long tail of ambiguities, but we can’t entirely cut it off. Any hourglass-shaped architecture must be prepared to invest a bit of continuous effort into gardening its interoperability, slowly but surely shaving down the semantic ambiguities within the common format.

The protocol force

Here’s a riff on the “hourglass model” conversation I’ve had with Bernhard Seefeld a while back. I only recently connected it with my earlier mumblings about software layering, and here’s what came out.

If a technology stack is arranged in such a way that there are consumers of value on one end of the stack and producers of it on the other, then at a certain scale, there emerges a force that encourages one middle layer of the stack – the waist – to be as  thin as possible. There will be a distinct preference for lower diversity of offerings at that layer. IP, HTTP, and HTML are all great examples of this force’s effects.

I am going to call this force the “protocol force”, since the outcome of this force is usually a common protocol or format that is used for communicating across that layer. 

To sketch out the mechanics behind the protocol force, the upper layers want to have access to more consumers, and those are only accessible through the lower layers. The lower layers want to get more producers, and only the upper layers can provide those. To get either, the layers have to go through the waist, and they all want to minimize the cost of bridging, of implementing all the permutations that enable consumers and producers to interact with each other. Put differently, everyone wants to spend as little as possible to reach as many consumers/producers as possible.

For instance, if we have multiple interaction protocols available in the waist layer, a growth spurt of an ecosystem of producers and consumers around this layer will trigger the  “winner takes all” dynamics: a protocol that gets some critical mass of consumers (or producers) will reduce the appeal of using other protocols. As these other protocols will fall into disuse, the one that “won” will continue to gain new adopters  – thus thinning the waist layer.

Interestingly, this protocol force may not manifest in the adjacent layers, even if they look like the connectors between the upper and the lower layers. As long as there’s one layer that is thin, the adjacent layers may enjoy high diversity of offerings. 

A good example of this is the Web frameworks. There are always so many of them, right? Why is that? My explanation of this phenomenon, applying the reasoning above, is that they are protected from the effect of the protocol force by the Web Platform layer (the HTML/CSS/JS combo that we all love and enjoy) that sits right underneath them. This layer is incredibly thin: thanks to the set of circumstances and sheer designers’ luck, we only have one Web Platform.

Because of that, there can be a cornucopia of Web frameworks: as long as what they output is Web Platform-compatible, they won’t experience the pressure to agglomerate or race to the bottom.

The protocol force will be present in any layered stack that has producers and consumers as outer layers. One of the bridging layers will succumb to it. If we’re designing a layered system, we are better off preparing for this force to tap us on the shoulder and ask us to pick a layer to squish. Any resistance is futile. Might as well plan for it.

One of my favorite recent examples of such a design is the Protocol Buffers, a framework that Google uses internally to connect disparate pieces of functionality into one coherent whole. As long as a program speaks protos, it can mingle in Google-land. Whether intentionally or not, protocol buffers serve as the waist layer of Google infrastructure.

One of the key challenges of designing something as versatile as the Web Platform or protocol buffers is the fact that this layer will be the most used and, sadly. abused part of our stack. Once squished into a thin waist, this layer becomes the great enabler of our future – or the source of our doom. Its flexibility and capacity to convey the intentions of developers will be constantly tested and stretched and often broken. This is a sign of success and a good thing. As long as we’re prepared to invest into continuously improving and developing the waist of our stack, we can harness the protocol force to help us, rather than hinder.

Why AI orchestration

Why do I find the problem of AI patterns and more generally, AI orchestration so interesting that I literally started building a framework for it? Why do we even need graphs and chains in this whole AI thing? My colleagues with a traditional software engineering background have been asking me this question a lot lately.

Put very briefly, at the height of the current AI spring that we’re experiencing, orchestration is a crucial tool for getting AI applications to the shipping point.

To elaborate,  imagine that an idea for a software application takes a journey from inception to full realization through these two gates.

First, it needs to pass the “hey… this might just work” gate. Let’s call this gate the “Once” gate, since it’s exactly how many times we need to see our prototype work to get through it.

Then, it needs to pass through the “okay, this works reasonably consistently” gate. We’ll call it the “Mostly” gate to reflect the confidence we have in the prototype’s ability to work. It might be missing some features, lack in polish and underwhelm in performance benchmarks, but it is something we can give to a small group of trusted users to play with and not be completely embarrassed.

Beyond these two gates, there’s some shipping point, where the prototype – now a fully-fledged user experience – passes our bar for shipping quality and we finally release it to our users.

A mistake that many traditional software developers, their managers, and sponsors/investors make is that, when looking at AI-based applications, they presume the typical cadence of passing through these gates.

Let’s first sketch out this traditional software development cadence as a sequence below.

The “Once” gate plays a significant role, since it requires finding and coding up the first realization of the idea. In traditional software development, passing this gate means that there exists a kernel of a shipping product, albeit still in dire need of growing and nurturing.

The trip to the “Mostly” gate represents this process of maturing the prototype. It is typically less about ideation and mostly converging on the robust implementation of the idea. There may be some circuitous detours that await us, but more often than not, it’s about climbing the hill.

In traditional software development, this part of the journey is a matter of technical excellence and resilience. It requires discipline and often requires a certain kind of organizing skill. On more than one occasion, I’ve seen brilliant program managers brought in, who then help the team march toward their target with proper processes, burndown lists, and schedules. We grit our teeth and persevere, and are eventually rewarded with software that passes the shipping bar.

There’s still a lot of work to be done past that gate, like polish and further optimization. This is important work, but I will elide it from this story for brevity.

In AI applications, or at least mine and my friends/colleagues’ experiences with it, this story looks startlingly different. And definitely doesn’t fit into a neat sequential framing.

Passing the “Once” gate is often a matter of an evening project. Our colleagues wake up to a screencast of a thing that shouldn’t be possible, but somehow is. Everyone is thrilled and excited. Their traditional software developer instincts kick in: a joyful “let’s wrap this up and ship it!” is heard through the halls of the office.

Unfortunately, when we try to deviate even a little from the steps in the original screencast, we get perplexing and unsatisfying results. Uh oh.

We try boxing the squishy, weird nature of large language models into the production software constraints. We spend a lot of time playing with prompts, chaining them, tuning models, quantizing, chunking, augmenting – it all starts to feel like alchemy at some point. Spells, chants, and incantations. Maaaybe – maybe – we get to coax a model to do what we want more frequently. 

One of my colleagues calls it the “70% problem” – no matter how much we try, we can’t seem to get past our application producing consistent results  more than 70% of the time. Even by generous software quality standards, that’s not “Mostly”.

Getting to that next gate has little resemblance to the maturation process from traditional software development. Instead, it looks a lot more like the looping over and over back to “Once”, where we rework the original idea entirely and change nearly everything.

When working with AI applications, this capacity to rearrange everything and stay loose about the details of the thing we build, this design flexibility is what dramatically increases our chances of crossing to “Mostly” gate. 

Teams that hinge their success on adhering to the demo they sold to pass through the “Once” gate are much more likely to never see the next gate. Teams that decide that they can just lay down some code and improve iteratively – as traditional software engineering practices would suggest – are the ones who will likely work themselves into a gnarly spaghetti corner. At least today, for many cases – no matter how exciting and tantalizing, the “70% problem” remains an impassable barrier. We are much better off relying on an orchestration framework to give us the space to change our approach and keep experimenting.

This is a temporary state and it is not a novel phenomenon in technological innovation. Every new cycle of innovation goes through this. Every hype cycle eventually leads to the plateau of productivity, where traditional software development rules.

However, we are not at that plateau yet. My intuition is that we’re still climbing the slope toward the peak of inflated expectations. In such an environment, most of us will run into the “70% problem” barrier head-first. So, if you’re planning to build with large language models, be prepared to change everything many times over. Choose a robust orchestration framework to make that possible.

Makers and Magicians

I want to finally connect two threads of the story I’ve been slowly building across several posts. I’ve talked about the rise of makers. I’ve talked about the magicians. It’s time to bring them together and see how they relate to each other.

First, let’s paint the picture a little bit and set up the narrative.

The environment is ripe for disruption: there’s a new software capability and a nascent interface for it, and there’s a whole lot of commotion going on at all four layers of the stack. Everyone is seeing the potential, and is striving to glimpse the true shape of the opportunity, the one that brings the elusive product-market fit into clarity.

As I asserted before, there’s a brief moment when this opportunity is up for grabs, and the ground is more level than it’s ever been. Larger companies, despite having more resources, struggle to search for the coveted shape quickly due to the law of tightening aperture. Smaller startups and hobbyists can move a lot faster – albeit with high ergodic costs – and are able to cover more ground en masse. Add the combinatorial power of social networks and cozywebs, and it is significantly more likely that one of them will strike gold first.

For any larger player with strategic foresight, the name of the game is to “be there when it happens”. It might be tempting to try and out innovate the smaller players, but more often than not, that proves to be hubris.

Instead of trying to be the lucky person in the room, it is more effective to be the room that has the most exceptionally lucky person in it – and boost their luck as much as possible.

When the disruption does finally occur and the hockey stick of growth streaks upward, such a stance reduces the chances of counter positioning and improves the larger player’s ability to quickly learn from the said lucky person.

Put simply, during such times of rapid innovation, the task of attracting “exceptionally lucky people” to their developer ecosystems becomes dramatically more important for larger companies.

If the story indeed is playing out like so, then the notion of magicians is useful to identify those “exceptionally lucky people” – because luck compounds for those who explore the space in a way that magicians do.

But where do makers fit in? A good way to think of it as overlapping circles of two groups: developers and makers.

We’ll define the first circle as people who develop software, whether professionally or as a hobby. Developers, by definition, use developer surfaces: APIs, libraries, juts, tools, docs, and all those bits and bobs that go into making software.

The second circle is broader, because it includes folks who both develop and interact with software in a way that creates something they care about. Makers and developers obviously overlap. And since “maker” is a mindset, the boundary between makers and developers is porous: I could be a developer during the day and a maker at night. At the same time, not all developers are makers. Sometimes, it’s really just a job.

Makers who aren’t developers tend to gravitate toward becoming developers over time. My intuition is that the more engaged they become with the project, the more they find the need to make software, rather than just use it. However, the boundary that separates them from developers acts as a skill barrier. Becoming a developer can be a rather tough challenge, given the complexity of modern software.

Within these two circles, early adopters make up a small contingent that is weighted a bit toward makers. Based on how I defined maker traits earlier, it seems logical that early adopters will be primarily populated by them.

A tiny slice of the early adopter bubble on the diagram is magicians. They are more likely to be in the developer circle than not, since they typically have more expertise and skill to do their magic. However, there are likely some magicians hiding among non-developer makers, prevented by the learning curve barrier from letting their magic shine.

I hope this diagram acts as a navigational aid for you in your search for “exceptionally lucky” people – and I hope you make a room for them that feels inviting and fun to inhabit.

Zones of LLM predictability

As you may know, large language models (LLMs) are smack dab in the middle of my tangle of interests presently, so you can bet I spend a lot of time talking with my friends and colleagues about them. One lens that seems to have resulted in fruitful conversations is the one related to predictability of output.

In this lens, we look at the LLM’s output as something that we can predict based on the input – and the reaction we might have on the outcomes. If we imagine a spectrum where the results are entirely unpredictable at one extreme, and can be predicted with utter certainty at the other – then we have a space to play in.

For a simple example, let’s suppose we’re asking two different LLMs to complete the sentence “roses are red, violets are …”. If one LLM just returns a bunch of random characters, while the other consistently and persistently says “blue”, we kind of know where we’d place these models on the spectrum. The random character one goes closer to an unpredictable extreme and the insistent blue one goes closer to the perfectly predictable end.

For ease of navigating our newly created space, let’s break it down into four zones: chaotic, weird, prosaic, and mechanistic. 

🌫️ Chaotic

In the chaotic zone dwell the LLMs that basically produce white noise. They aren’t really models, but random character sequence generators.  By the way, I asked Midjourney illustrate white noise, and it gave me this visage:

(It’s beautiful, Midge, but not what I asked for)

This zone is only here to bookend the very extreme of the spectrum. Suffice to say that we humans tend to only use white noise as means to an end, mostly judging it as useless on its own.

🐲 Weird

The adjacent zone is where the model outputs something that is weird and bizarre, yet strangely recognizable and sometimes even almost right. Remember the whole “hands” thing in the early generative imagery journey? That’s what I am talking about.

(“A normal human hand with five fingers” – whoopsie!)

This zone is where LLMs are at their creative best. Sure, they can’t count fingers, and yes, some – many! – outcomes are creepy and disturbing, but they also produce predictions that are just outside of the norms, while still retaining some traits that keep them outside of the chaotic zone. And that stirs creativity and inspiration in those who observe these outcomes. This is the zone where a model is more of a muse – odd and mysterious, and not very serious. Yet, when paired with a creative mind of a human, it can help produce astounding things.

📈 Prosaic

The prosaic zone is where an LLM produces mostly the results we expect. It might add a bit of flourish in bursts of creativity and insert an occasional (very safe) dad joke, but for the most part, that’s the zone that I also sometimes call the “LLM application zone”. If you ever spend time getting your retrieval-augmented generation to give accurate responses, or only return code results that can actually run – you’ve lived in this zone.

(“a happy software engineer working, stock photo” – oh yes, please! More cliche!)

My own explorations are mostly in this zone. The asymptotes I outlined earlier this year are still in place, and holding. If anything, time has shown that these asymptotes are firmer than I initially expected.

⚙️ Mechanistic

Another bookend of the spectrum is the mechanistic zone. At this point, LLM output is so constrained and deterministic that we become uncertain if using an LLM is even necessary: we might be better off just writing “old school” software that does the job.

The mechanistic zone is roughly the failure case for the current “AI” excitement. Should the next AI winter come, we’ll likely see most of the use cases shift toward this zone: the LLM either constrained, significantly scaled down in size, or entirely ripped out, replaced with code.

💬 A conversation guide

Now that we have the zones marked in the space, we can have conversations about them. Here are some interesting starter questions that generated insights for me and my colleagues:

  • How wide (or narrow) is each zone? For example, I know a few skeptics that don’t even believe that the Prosaic zone exists. For them, its width is zero.
  • How much value will be generated in each band? For instance, the Prosaic zone  is where most of the current attention seems to be. Questions like “Can we make LLMs be useful at an industrial scale? How much value can LLMs produce?” seem to be on everyone’s mind.
  • How will the value generated look for each band? What type of value comes out of the Weird zone? What about the Prosaic zone?
  • What kind of advancements – technological or societal – would it take to change the proportions of the zones?

For more adventurous travelers, here are more questions that push the boundaries of the lens:

  • What does “predictable”even  mean? If I know English, but don’t have the cultural background to recognize the “Roses are Red” ditty, I might find the “blue” perplexing as a completion. Violets are kind of purplish, actually.
  • What do judgments about predictability of the LLM output tell us about the observer? What can we tell about their expectations, their sense of self, and how they relate to an LLM?
  • What is it that LLMs capture that makes their output predictable? What’s the nature of that information and what might we discern about it?

As you can tell, I am pretty intrigued by the new questions that large language models surface to us. If you’re interested in this subject as well, I hope this lens will be useful to you.

Doers, Thinkers, and Magicians

I’ve been reflecting on my experiences of working with developers and developer ecosystems, and I realized that there’s a really interesting twist on the typical “early adopter” story that’s been hiding in the back of my mind.

Let’s suppose that you and I are spinning up a new developer experience project. We have a fledgling developer surface that we’re rapidly shaping and growing, and trying to to get it right by making contact with its intended audience.

The very first of these developers are commonly called early adopters, which originated from Everett Roger’s book Diffusion of Innovations. It is my experience that these early adopters can be further broken into three subgroups: doers, thinkers, and magicians – and the presence of all three is required for the developer surface to successfully navigate toward broad adoption and bring forth our hopes and dreams for it. 

More than that, the mix of these subgroups heavily influences the arc that the project will follow, the pattern into which the developer ecosystem around the developer surface will settle into – should it succeed.

To explore this notion, let’s zoom in on each subgroup.

💪 Doers

The doer early adopters are typically the most populous sub-group. They are very easy to identify: they do stuff with our developer surface, making things with it, poking at it here and there.

Doers bring energy and create the sense of a bustling community emerging around technology or products, powered by technology. They are eager, excited, typically with some tinkering time to spare. They are boisterous, peppering technology or product builders with questions and suggestions. Most of their questions and feedback of a very practical nature: they just want to make our thing do their bidding.

Doers often don’t have enough technical skills to just start doing what they want – not just because our developer surface is new, but because there might be gaps in their understanding of the surrounding technologies. As such, they need patient and consistent investment of hand-holding, be that tutorials, hackathons, or individual support.

If our project has doers in the early adopter mix, we have a key ingredient. We have the potential energy that can be transferred into forward progress. This subgroup of early adopters provides valuable insights on the usability of the technology or product, and their contagious enthusiasm attracts new customers.

If our project doesn’t have doers, we might as well not have a project. The absence of doers in the early adopter mix is a warning sign that we might have come up with something that is deeply uninteresting, incomprehensible, or otherwise impossible to access by doers.

🧠 Thinkers

The thinker early adopters usually come in much smaller numbers than doers. In some ways, thinkers can be seen as a subset of doers, with a key distinction: they actually spend time imagining possibilities and exploring the possibilities of the technology they are studying. They might be playing with the developer surface themselves, but they could also just be observing doers and identifying interesting potentialities in the churning soup of ideation that the doers produce.

One of my first encounters with thinkers was back in the early 2000s, when blogs.msdn.com was introduced as part of Microsoft Developer Network. I was a fairly new doer-inclined developer myself, and I was fascinated by the blog posts from Dare Obasanjo or Nikhil Kothari on the then-nascent .NET framework. They moved from the pragmatic “here’s how you do <blah>” to open-ended cross-blog conversations about second order effects and implications of technology they were using, as well as introduced various completely new ideas into how it might be used. For me, whole new frontiers opened up and connections were made between concepts that I viewed as entirely unrelated – all the while making me ever more energized about the technology.

This is the role of the thinkers: they hold our developer surface in their hands lightly, turning this way and that, and applying intellect and curiosity to consider its potential.

When our project has thinker early adopters, we have acquired a source of more durable energy. While doers do introduce the initial energy, their explorations, being mostly pragmatic and practical, often peter out and lose steam without the influx of new ideas. Thinkers are the ones who introduce these new ideas, and reinvigorate the excitement and enthusiasm.

Not having thinkers as early adopters means that the project is in danger of getting stuck in a premature local maxima. When the doers uncover all the obvious use cases, these might not be the ones that propel our developer surface toward our intended destination – and we’ll have to contend with being stuck in what we view as “mediocre success” or just breaking down our camp and admitting defeat. It is the thinkers who help move doers move beyond the initial local maximas into adjacent areas that are more likely to hold the value we’re looking for.

✨ Magicians

The final ingredient in the early adopter mix are the magicians. The magician early adopters are even more rare. Even having one is an incredible stroke of fortune, and something that we are obliged to cherish.

The magicians are both doers and thinkers, but they have this weird knack for building amazing things that blow your mind. I wish I knew how that works. In the past, I attempted to grow magicians out of thinkers and/or doers, but there doesn’t seem to be a path from here to there.

The magicians are usually experienced and seasoned developers. They grasp the idea behind our developer surface in seconds, and intuitively see the landscape of opportunities. Then, they reach for the simplest path toward the opportunity that appears most valuable – and for some unfathomable reason – they are usually right. They connect bits and pieces of our stuff into something that suddenly looks solid and – this is a common effect – blindingly obvious. “What the hell?! How?! … Oh… Why didn’t I think of this before?!” is a common reaction to a magican’s artifact.

When I worked in Chrome Web Platform, I was very lucky to have a handful of these magicians around me. For some reason, the Chrome team’s DevRel contingent was rife with them. In a more recent memory, Simon Willison’s work on llm has the same magician quality.

The presence of magicians significantly strengthens our project’s chances of broad adoption. Like thinkers, the early adopter magicians uplevel the current understanding of what’s possible – but they do it in an explosive, revolutionary way. “Now <bar> is possible, here’s some code” – and everyone freaks out, dropping all the previous work, being able to not just imagine the potential of the next frontier, but actually try it. This explosive amount of energy that the magicians inject into a project can catapult it way beyond our initial intentions. We just need to be patient, hang on to our dear lives while the starship of a new idea streaks forward, and be ready to explore the crazy new planet it will land on.

Not every developer surface gets magician early adopters. A project can still be moderately successful even in the dearth of magicians. A very common side effect of that is that the developer community grows large and appears vibrant, but the outcomes it produces tend to be on the lower side of our expectations. Low-magician developer ecosystems tend to have very thin long tails, with only a few well-settled participants forming a narrow head.

🧪 The right mix

A reasonable question might be: what is the right mix for our project? Disappointingly, there is no satisfying answer. Developer-oriented projects, at least in my experience, all tend to follow roughly the same shape of proportions: lots of doers, a few thinkers, a couple – if any – of magicians. It is usually the presence of magicians and thinkers that significantly improves the chances of our project going somewhere good. So, if I could offer any advice to budding developer experience makers, it would be this: seek out the thinkers and the magicians. They are the key to passing through the early adoption stage.

Traits of a maker mindset

The whole concept of makers has been on my and my colleagues’ mind a lot, especially with their current rise in prominence with generative AI.  

A fun question popped out in one of the conversations: “How might one tell a maker from a non-maker?” The idea of a “non-maker” immediately felt a bit ridiculous. Since we’ve already established that “maker” is a mindset, it’s pretty clear that shifting out of that mindset is going to land us in a “non-maker” territory. But when we are in the maker mindset, what are the traits and characteristics that might stand out?

After talking to a few folks about this, a rough list started to emerge. It’s still not quite right, but I thought I would share it early for your perusal.

So far, I have four traits that seem to resonate whenever I talk about a “maker mindset” to others. These traits are option-seeking, craving creative friction, zagging, and optimism.

🔢 Option-seeking

When in the maker mindset, we tend to seek more options. If offered a single way to solve a problem, no matter how simple and elegant, a maker in me will perceive it with skepticism. There’s something about optionality and preserving the agency to choose these options that is highly important to a maker mindset. The more knobs, the merrier. The more choices, the more exciting. This is plainly in conflict with the mainstream theories of user experience for the common consumers. When I am in a non-maker mindset, I want a simple single solution that gets the job done. When wearing a maker hat, I will steer away from it.

This might be one of the reasons why open source projects and modular solutions are attractive to makers. Being able to pick and choose whichever pieces I want and combine them in whatever way I want – and have an option to change mind – are a big part of the whole maker experience.

💪 Craving creative friction

Very related, a maker mindset frowns on well-solved problems. We will rarely find makers tinkering with obvious or fully understood problem spaces. For makers,  things have to be difficult and challenging to be attractive. Too much polish is a bit of a letdown – it means that someone already solved all the fun problems. Maker mindset cherishes creative friction – the presence of a challenge in the process of making is what stirs creative juices.

This is why makers don’t mind messing with stuff that isn’t yet fully baked. One of my colleagues put it as “makers are in it for the problems, not solutions.” This is a bit too blunt, but I can’t disagree with the sentiment. For makers, it’s about the journey, though the tantalizing promise of a destination definitely helps.

🔀 Zagging

Makers love to zag when everyone zigs. When in the maker mindset, we tend to look for opportunities that are odd-shaped compared to what everyone else is seeking.

Makers rejoice when it looks like they’re doing something weird.  Being outside of the curve means that there’s a chance we’re ahead of it. Makers wholeheartedly take this chance. Even if zagging doesn’t pay off, the thrill of exploring the wilderness is a powerful force that animates makers.

When everyone is making an AI-powered chatbot, makers are playing with meta-reasoning and autonomous agents. When everyone finally catches onto the agents, makers move on to something else.

☀️ Optimism

This one I am least certain about. It definitely rings true, but I don’t know if the word “optimism” captures the gist. When in the maker mindset, we are driven by a belief that our actions will lead to some outsized outcomes. Somehow, somewhere, we will hit that exponential curve, and things will truly get out of control. There’s a sense of “it’s definitely not working now, but just wait and see” that is like fresh air for makers.

Many makers are techno-optimists, who – often implicitly – believe that technology will solve all problems and do more good than evil over the long run. After all, making something often means creating new technology – be it physical, organizational, or social. And definitely, most makers believe that making something is better than not making it. Making is art, and all maker’s art has purpose, animated by often completely unfounded confidence in better outcomes.

📐 Designing for makers

Despite this list being so unkempt, we can start gleaning some interesting insights about designing user experiences that attract makers.

Makers flip the script on the conventional wisdom of delivering polished, simple experiences to users. Steve Krug’s “Don’t make me think” turns into “Give me an interesting puzzle!” and sometimes into “Ooh, this mess of a product looks perfect for my project”. For makers, rough edges signal exciting possibilities. I am still learning what this all means, but it’s starting to feel that product design for makers is dramatically different from design for users not in the maker mindset.

If such a difference does indeed exist, it’s interesting to consider how a product might be perceived by the same person, but from different mindsets. And perhaps even more granularly: some tools I want to have lots of knobs and options and rough/unexplored edges, and some of them I just want to work, even when I am in the maker mindset.

It seems overwhelming – and likely foolhardy – to establish a precise taxonomy here. The only recipe I know is to have the maker’s intuition. To design for makers, one has to have accumulated a lot of experience of being a maker. There doesn’t seem to be any way around that.