OODA and Intentionthe same dayThe ability to make predictions is an astounding quality of retained-mode systems.…
The expectation gradient
Understanding2022Once the notion of a problem is sufficiently semantically disambiguated, we can…
Prediction errors and jank2021It seems that the retained mode is our way to compensate for…
The conflation of “what is” and “what should be” is not the only way in which our intentions impact our prediction error rate. Another source is the intentions that we’re unaware of. To better understand what happens, we are going on another side adventure. And yes, we might even get to cast trigonometry spells again. But first, let’s talk about expectation gradients.
The Suffering of Expectations2020I have been thinking about the relationship between expectations and suffering, and…
Transformational Learning2020Building on the ideas in The Suffering of Expectations, I want to…
If we view prediction error rate as a measure of the accuracy of our predictions after the fact, expectation gradient is our forecasting metric. An easy way to grok it is to visualize ourselves standing on a trail and looking ahead, trying to guess the gradient of the incline. Is there a hill up ahead, or is it nice and flat? Or perhaps a wall that we can’t scale? The gradient of the path ahead foretells us of the effort we’ll need to put into moving forward.
In a similar vein, the expectation gradient reflects our sense of the difference between our models of “what is” and “what should be.” It is our estimate of the steering effort: how much energy we will need to invest to turn “what is” into “what should be.” A gentle slope of the gradient reflects low estimated effort, and as the estimate grows, the slope becomes steeper. If I find myself in a forest, facing a hungry tiger, I am experiencing a very steep gradient. Sitting in a comfortable chair while sipping eggnog (it is that time of the season!) contentedly and writing, however — that’s the definition of a gentle gradient slope for me.
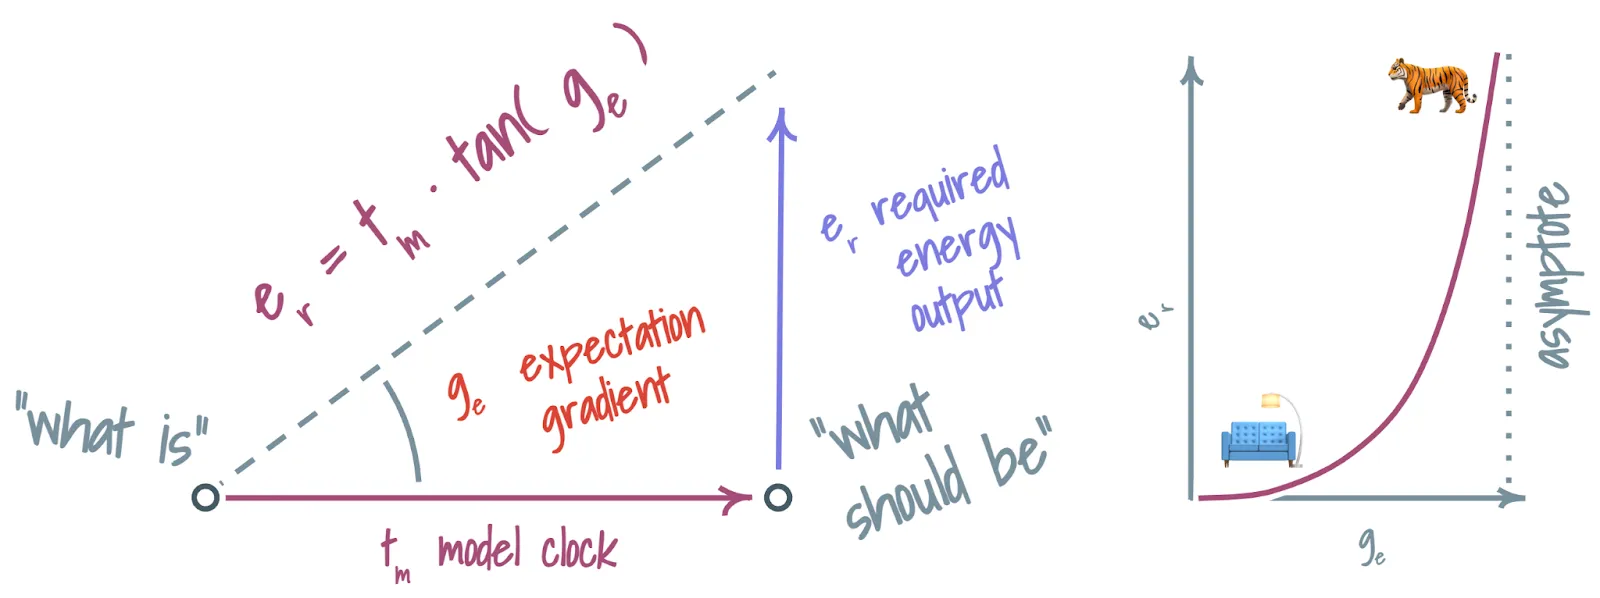
With our trig hat on, we can picture the expectation gradient as the angle of a triangle. The adjacent side is the distance between “what is” and “what should be” (or a fraction thereof), and the opposite side is the measure of the required energy that we need to muster to steer the environment from “what is” to “what should be.”
AI Developer Experience Asymptotes2023Below is my map of the asymptotes. This is not a complete…
The opposite-adjacent relationship to the angle is a tangent. When we deal with tangents, we face impossibilities. There is an asymptote, built into that little arrangement. The wavy tangent line starts slow, but then zooms into the sky, never ever quite fulfilling the promise of meeting required output.
Asymptotes and Value Niches2023Why AI orchestration2023OO and DA2021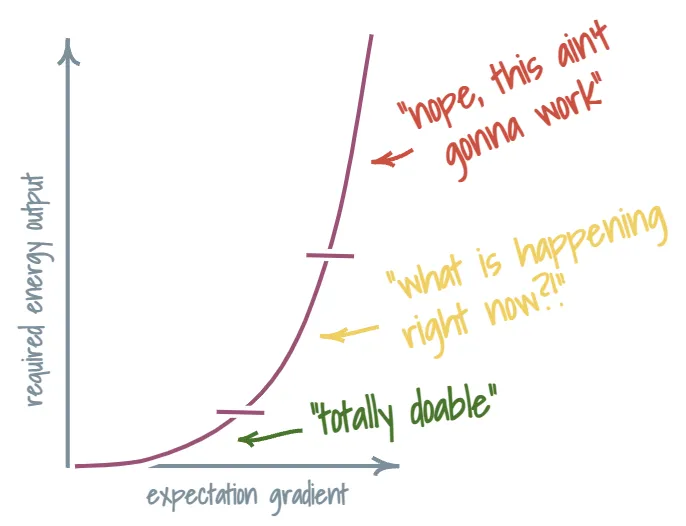


Behavior over time graphs and ways to influence2022If our BOTG curve needs to touch and stick to — or…
Embrace the suck2022Picture a simple framework. There are three attributes that can have positive…
I quite like this framing, because it feels pretty intuitive. The curve practically begs to be broken down into three distinct sections: the section before the kink where we’re reasonably certain that we can achieve our goal, the middle section where we are are uncertain of the outcome, and the asymptote – the section in which we’re pretty certain that our goal is unachievable.
Separating cargo from the train2023I’ve been puzzling over a problem that many engineering teams face and…
Nudges, boosts, bumpers, and tilts2023Using these two properties as axes, we can draw a nice –…
The OODA insidethe same day, links hereBecause of the way we humans are wired, the expectation gradient is…
Model flatteninglinks here, 2021If we look into the strategies that the inner OODA loop applies…
Cravings and Aversionslinks here, 2021Each of these remembered experiences skews our sense of the expectation gradients.…
Janklesslinks here, 2021Not to be flip about it, but a sure way to eliminate…
Silly mathlinks here, 2022Silly math is a bit more recent, but it’s something I enjoy…
Being Strategiclinks here, 2022We forget to look back at the original intentions and check if…
Looking at “dancing with delusion” from the previous piece through the lens of expectation gradient, it’s all about convincing the team that the road ahead is mostly out of the third section, stretching the “uncertain” a bit longer.
Show 5 comments
The OODA inside – Dimitri Glazkov linked here · December 10, 2021
[…] of the way we humans are wired, the expectation gradient is not a neutral measurement. For some reason, when we perceive a tiger eyeing us voraciously, our […]
Model flattening – Dimitri Glazkov linked here · December 16, 2021
[…] we can loosely identify three, each of non-linearly increasing severity, neatly following that expectation gradient tangent […]
Cravings and Aversions – Dimitri Glazkov linked here · December 17, 2021
[…] of these remembered experiences skews our sense of the expectation gradients. When we encounter a similar situation in the future, these deep marks influence how we evaluate […]
Jankless – Dimitri Glazkov linked here · December 23, 2021
[…] with the environment around us, the “what is” and “what should be” are the same. Our expectation gradient is zero. Frankly, this is never true for us humans: our aim is always a bit off that perfect Zen […]
Silly math – Dimitri Glazkov linked here · January 6, 2022
[…] Silly math is a bit more recent, but it’s something I enjoy just as much. Turns out, an equation can sometimes convey an otherwise tricky dynamic. Addition and subtraction are the simplest: our prototypical “sum of the parts.” Multiplication and division introduce nonlinear relationships and make things more interesting. The one that I find especially fascinating is division by zero. If I describe growth as effort divided by friction, what happens when friction evaporates? Another one that comes handy is multiplication of probabilities. It is perfectly logical and still kind of spooky to see a product of very high probabilities produce a lower value. Alex Komoroske used this very effectively to illustrate his point in the slime mold deck (Yes! two mentions of Alex’s deck in two consecutive pieces! Level up!) And of course, how can we can’t forget exponential equations to draw attention to compounding loops?! Basic trigonometry is another good vehicle to share mental models. If we can sketch out a triangle, we can use the sine, cosine, or tangent to describe things that undulate or perhaps rise out of sight asymptotically. In the series, I did this a couple of times when talking about prediction errors and the expectation gradient. […]